More about HKUST
17 Oct 2022
11:00am - 12:00pm
Seminar, Lecture, Talk

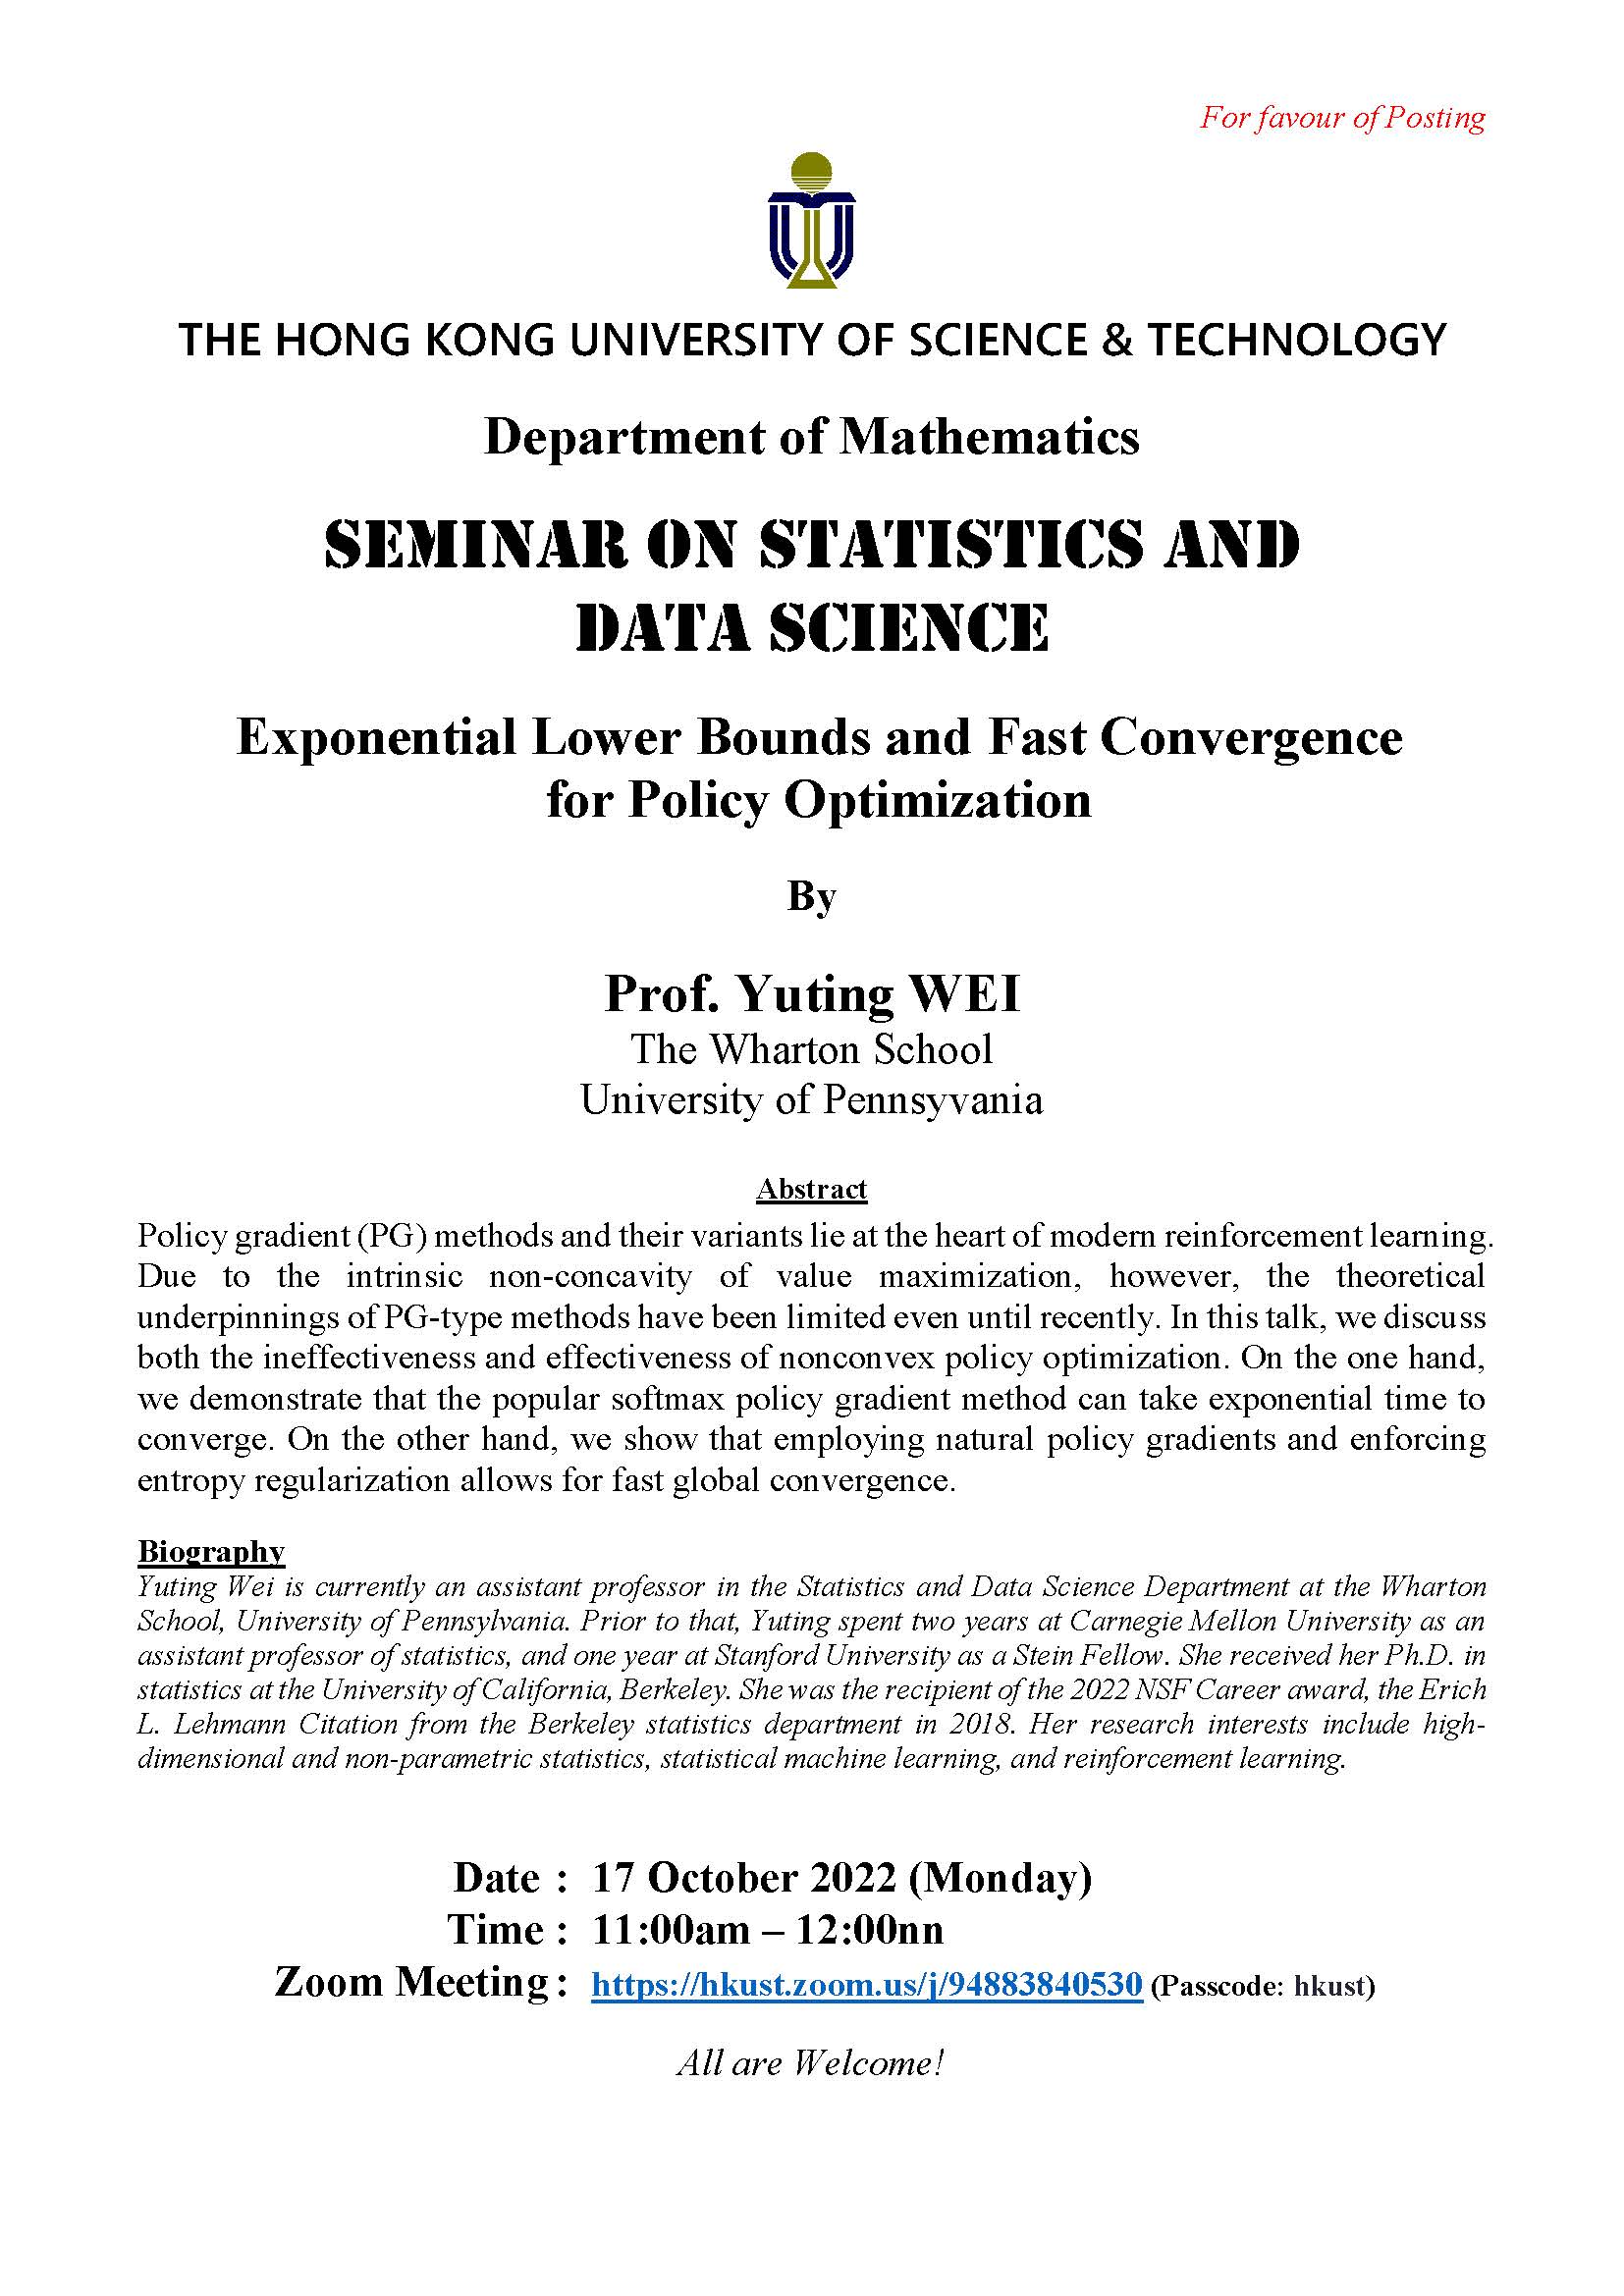
Policy gradient (PG) methods and their variants lie at the heart of modern reinforcement learning. Due to the intrinsic non-concavity of value maximization, however, the theoretical underpinnings of PG-type methods have been limited even until recently. In this talk, we discuss both the ineffectiveness and effectiveness of nonconvex policy optimization. On the one hand, we demonstrate that the popular softmax policy gradient method can take exponential time to converge. On the other hand, we show that employing natural policy gradients and enforcing entropy regularization allows for fast global convergence.
17 Oct 2022
11:00am - 12:00pm
Where
https://hkust.zoom.us/j/94883840530 (Passcode: hkust)
Speakers/Performers
Prof. Yuting WEI
The Wharton School, University of Pennsyvania
The Wharton School, University of Pennsyvania
Organizer(S)
Department of Mathematics
Contact/Enquiries
Payment Details
Audience
Alumni, Faculty and staff, PG students, UG students
Language(s)
English
Other Events
6 Nov 2026
Seminar, Lecture, Talk
IAS/ School of Science Joint Lecture - Drag on a Penetrable Disk in a Superfluid
Abstract
The motion of a body through a superfluid can generate phenomena distinct from a normal viscous fluid. This includes the absence of drag below a critical body speed with the shedding o...
16 Jun 2026
Seminar, Lecture, Talk
IAS / School of Science Joint Lecture - Shaping Tumor Cell Plasticity and Therapy Resistance in Glioblastoma
Abstract
Tumor heterogeneity fueled by plasticity and genetic diversification of cancer cells is key to therapy failure of malignant glioma. The speaker's team implemented spatial and genetic p...